Evals and LLM-as-a-Judge
Evals turn variable model behavior into an evidence problem, combining deterministic checks, outcome verification, repeated trials, human review, and LLM judges without confusing a score with correctness.
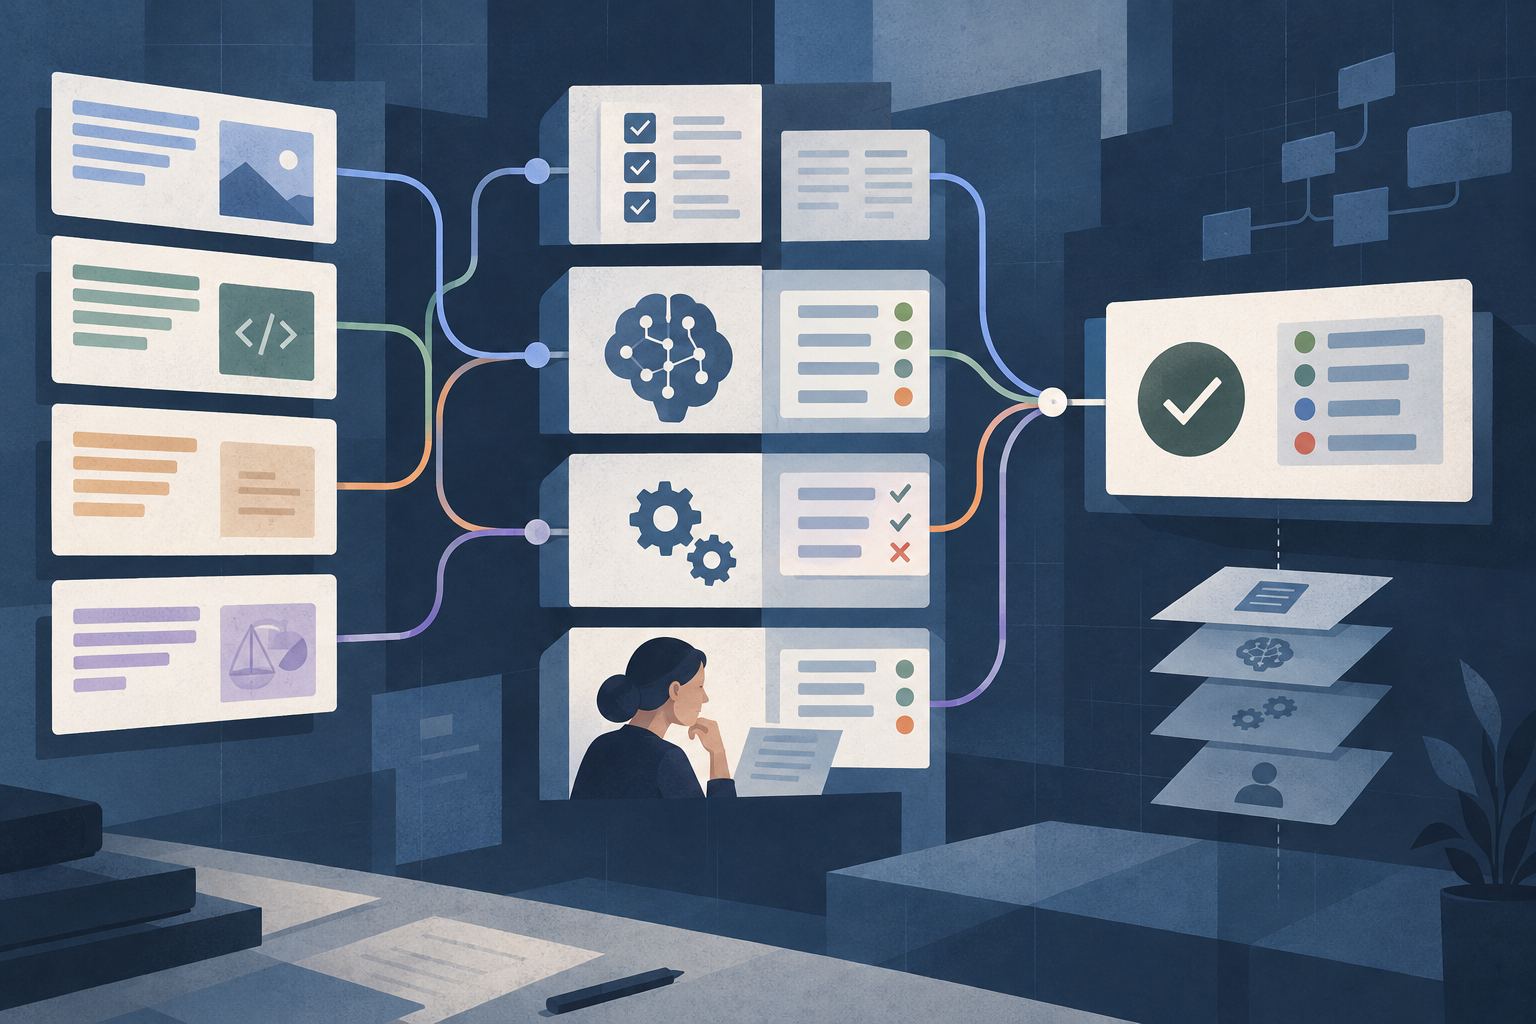
Evals and LLM-as-a-Judge
How Do We Test Software Without One Correct Output?
A software test usually has an oracle. Give the program an input, observe the result, and compare it with something known: an expected value, an invariant, a database state, a type constraint, or a human acceptance decision.
Model-mediated software makes the oracle harder to define. The same request can have several valid answers. A research report can be accurate without matching a reference paragraph. A support agent can resolve a problem through more than one valid sequence of tool calls. An agent can produce a good result through a path its designer did not anticipate.
That does not make testing impossible. It makes the evaluation surface wider.
An eval is a repeatable test procedure that runs a system on a defined task and applies one or more grading rules to measure success. An LLM-as-a-judge is a model-based grader that evaluates a response, trace, or artifact against a rubric, a reference, or another candidate.
The useful distinction is simple: an eval is the whole measurement system. An LLM judge is one instrument inside it.
This is Post 14 in The Abstraction Shift: How Software Keeps Moving Up.
Why This Exists
The first version of a model feature often appears to work through a handful of examples. A prompt is written, a model returns a plausible answer, and the feature owner moves on.
That confidence has a short half-life. A model changes. A system prompt grows. A retrieval index is refreshed. A tool schema is revised. A new routing rule changes the context. A latency budget causes the agent to stop earlier. An evaluator rewards a style that hides unsupported claims.
Without a durable evaluation suite, each change is reviewed through memory and anecdotes. Failures are discovered in production, and a fix for one case can quietly damage another.
Evals exist to make behavior comparable across changes. They provide a shared test set for product, engineering, research, security, and operations. They turn a vague request such as “make the agent better” into a set of observable questions:
- Did it complete the task?
- Did it preserve required policy and safety constraints?
- Did it use authoritative evidence?
- Did it produce an acceptable answer or artifact?
- Did it take a valid or unnecessarily expensive path?
- Did it leave the environment in the correct state?
- Did the improvement hold across repeated trials and difficult cases?
The questions are related, but they are not interchangeable. A fluent answer can be unsupported. A correct answer can be reached through a wasteful path. A successful booking message can be emitted even when no reservation exists. A safe refusal can be rated poorly if the rubric rewards helpfulness without representing authorization.
Evaluation makes those distinctions explicit.
What We Did Before
Software testing already used unit and integration tests, properties, benchmarks, acceptance review, and production monitoring. Those methods remain valuable. The difficulty is that a model-mediated system may produce several plausible paths and outputs, and its environment may vary between runs.
The evaluation problem therefore moves from checking one expected response to defining observable success across the response, the trace, the environment, and the operating envelope.
What Is an Eval?
An eval is a repeatable procedure that runs a system on a defined task set and gathers evidence about whether it behaved acceptably. Keep these parts distinct:
- Task: the requested behavior and constraints.
- Trial: one run in a named system and environment.
- Harness: the code that resets, runs, and records the trial.
- Trace: the decisions, tool calls, context, and intermediate events.
- Outcome: the state that actually resulted.
- Grader: a deterministic check, rubric, model judge, or human review.
- Suite: the versioned collection of tasks and grading rules.
A score summarizes evidence. It is not the definition of correctness.
The Test Oracle Is the Hard Part
Choose the strongest oracle available for each requirement:
- exact checks for schemas, identifiers, and required fields;
- state or property checks for invariants and side effects;
- reference checks for grounded claims and expected artifacts;
- rubrics for quality dimensions that require interpretation;
- human review where the consequence or ambiguity exceeds automated confidence.
Use a model judge to interpret evidence, not to replace a source-of-truth check.
Four Evaluation Surfaces
Evaluate more than the final answer:
- Response: Is the explanation accurate, useful, and appropriately uncertain?
- Trace: Did the system choose permitted tools, evidence, and stopping points?
- Outcome: Did the environment reach the intended state?
- Envelope: Did latency, tokens, retries, and reviewer effort stay within bounds?
A polished response can hide a wrong action. A correct outcome can still expose an unacceptable path. Keep the surfaces separate.
Reliable evaluation inspects what the system said, how it acted, what changed, and what the result cost.
What Is LLM-as-a-Judge?
An LLM judge applies a model to open-ended evidence using a defined rubric. It can compare candidates, assess a response against references, or inspect a trace and artifact. It is useful when exact checks cannot express the requirement, but it remains another probabilistic component.
Give the judge narrow inputs, explicit evidence, a scoring rubric, and an abstention path. Test for position bias, verbosity bias, self-preference, and sensitivity to irrelevant formatting. Never let a judge override a deterministic fact about authorization, state, or side effect.
Where the Analogy Breaks
A score is not correctness
A score is evidence generated by a procedure. It is not the property itself.
If the judge scores an answer highly, the result means that this judge, with this rubric and this supplied context, found the answer acceptable. It does not prove that every claim is true, that the user is authorized, or that an external action occurred.
Treat the score as one observation in a measurement system. Keep the raw output, rubric version, judge model, prompt version, and evidence used so the observation can be audited.
Fluency can masquerade as quality
Language models often produce confident, well-structured prose. A judge may reward the same surface qualities even when the content is incomplete or false.
Put factual and policy checks before style scoring. Ask the judge to identify evidence, state when it cannot determine a criterion, and fail closed on critical requirements.
Agreement can be correlated error
Several model judges may share the same training data, prompt assumptions, and blind spots. Agreement among them can be reassuring without being independent.
Use different evidence, models, prompts, or review methods when independence matters. An exact state check and an LLM rubric are more complementary than three nearly identical model calls.
The judge can prefer its own kind
Research on model-based evaluation has identified position, verbosity, and self-enhancement biases among other limitations. A judge may prefer a longer answer, the answer shown in a favored position, or an output that resembles its own style.
Mitigations reduce but do not eliminate the problem. Randomize candidate order, blind irrelevant metadata, test the judge on known pairs, limit the rubric to observable criteria, and compare its decisions with human review.
The judge may be easier to optimize than the task
Once a score becomes a target, systems can learn to satisfy the rubric’s surface signals. A response may include ceremonial caveats, repeat key phrases, or produce citations that look plausible without improving the underlying result.
The evaluation needs hidden cases, adversarial cases, outcome checks, and periodic human review. A system should not receive full credit for describing a successful action when the environment disagrees.
The path may be valid without being familiar
An agent can find a valid solution through a tool sequence that the test designer did not imagine. A brittle path assertion can mark that behavior as failure.
Test invariant properties and final outcomes unless the sequence itself is a requirement. When order matters for safety, encode the actual safety constraint, such as approval before commit, instead of encoding one incidental implementation path.
The task can be wrong
An evaluation can fail the system for obeying the task as written, or pass a shortcut that violates the task’s intent. Ambiguous prompts, incorrect references, flaky environments, and grader bugs create false conclusions.
Review tasks and graders as production code. A surprising score should trigger investigation of the harness before a confident claim about the model.
Calibrating the Judge
Calibrate the judge against qualified human review before using it for release decisions:
- label a representative sample, including difficult and adversarial cases;
- compare agreement and disagreement by slice, not only by average score;
- test irrelevant changes such as candidate order, verbosity, and formatting;
- give the judge a clear abstention and escalation path;
- version the rubric, judge, task set, and calibration evidence together.
Disagreement is diagnostic evidence about the task or rubric, not merely noise to average away.
Under the Hood
A production evaluation system can be described as eight stages:
1. Define the behavior
State the user goal, task boundary, allowed capabilities, source of truth, critical constraints, and acceptable outcomes. Write down what must never happen.
2. Build the task set
Create representative, edge, adversarial, and regression tasks. Include tasks that should be easy, tasks that require deeper work, and tasks where the safest result is a refusal or escalation.
Keep the evaluation set separate from any tuning or prompt-development examples when leakage would make the score misleading.
3. Construct the harness
Reset or provision the environment, invoke the real runtime, apply the real permissions, and capture the trace and outcome. Make retries, timeouts, and side effects explicit.
For destructive capabilities, use a sandbox, a simulator, or a transactional test environment. An eval should not create real harm merely to produce a score.
4. Choose the oracles
Use exact checks, schema validation, unit tests, state queries, static analysis, trace assertions, model rubrics, and human review according to the property being measured.
Put a deterministic check in front of a model judge whenever the requirement can be expressed deterministically.
5. Run repeated trials
Run enough trials to observe variance. Record the distribution, not just the mean. A system that passes 95 percent of cases with a 50 percent success rate on one important task may not meet the product’s reliability requirement.
The right number of trials depends on the decision, cost, and acceptable uncertainty. High-consequence behavior deserves stronger evidence than a low-risk copy-editing feature.
6. Grade each surface
Score the final response, trace, outcome, and resource envelope independently before aggregating. Preserve partial credit where it helps diagnose progress, but keep critical failures visible.
7. Investigate the failures
Group failures by cause: missing context, retrieval error, tool selection, policy violation, judge disagreement, environment flakiness, timeout, cost, unsupported claim, or task ambiguity.
The purpose of an eval is not to produce a leaderboard. It is to show which part of the system needs to change.
8. Decide and learn
Compare with a baseline, apply release thresholds, send uncertain cases to review, and add meaningful new failures to the suite. An eval should improve the system’s next iteration, not just label its current state.
A Concrete Example
Consider a support agent that receives a request to refund a duplicate charge.
The agent may need to:
- identify the customer and order;
- inspect the payment record;
- distinguish a duplicate from two legitimate purchases;
- apply the refund policy;
- ask for approval when the amount exceeds the agent’s limit;
- process the refund through a payment tool;
- explain the result clearly.
The final response is only one part of success. A useful task defines a controlled test environment with a customer, order, payment records, policy version, and payment service simulator.
The harness can run the agent and collect:
- the complete model and tool trace;
- the payment and ticket state after the run;
- the final response;
- latency, token count, tool calls, retries, and cost.
The graders can then be split by responsibility:
- a state check verifies that the correct payment was refunded exactly once;
- a policy check verifies that identity and approval requirements were met;
- a trace check verifies that the agent did not call the refund tool before authorization;
- a model rubric grades whether the response explains the outcome accurately and respectfully;
- a human sample checks whether the rubric and automated results match expert judgment.
An agent that says “Your refund is complete” without changing the payment state fails, regardless of how persuasive the message sounds. An agent that completes the refund safely but explains the delay poorly may pass the critical action criteria while receiving a lower communication score. The result is more useful than one blended five-point rating because it tells the operator what to fix.
The same structure applies to other domains. A coding agent needs tests and repository state. A research agent needs claim support, source authority, coverage, and uncertainty. A computer-use agent needs a verified environment outcome and a record of every action. A multi-agent system needs coordination traces and aggregation checks in addition to the individual worker results.
Failure Modes
Happy-path confidence
A small suite passes while edge cases, adversarial inputs, and partial failures remain untested. Include slices that represent the real operating envelope.
Reference overfitting
The system learns to resemble a reference answer without satisfying the underlying task. Combine reference checks with properties, outcomes, and human review.
Judge bias or drift
A model judge may favor verbosity, familiar phrasing, its own style, or a changed rubric. Recalibrate after judge, prompt, model, or task changes.
Path and outcome blindness
A good final response can conceal an unauthorized action, and a valid path can still fail to change the environment. Grade traces and source-of-truth outcomes separately.
Single-trial certainty
Variable systems can pass once and fail later. Repeat trials, report variance, and preserve the system, environment, and budget versions.
Cost denial
Quality gains that exceed latency, token, tool, or reviewer budgets are not production improvements. Treat the operating envelope as part of the evaluation.
Sources
- Demystifying evals for AI agents, Anthropic: defines tasks, trials, graders, traces, outcomes, harnesses, and suites; compares code-based, model-based, and human graders; discusses repeated trials, partial credit, calibration, and evaluation bugs.
- Evals API reference, OpenAI: documents evaluations as reusable testing criteria over data sources, with multiple grader types and repeatable runs.
- Graders API reference, OpenAI: documents string, similarity, Python, model-based, label, and multi-graders, including combining several signals.
- Building effective agents, Anthropic: provides the workflow and agent-pattern lineage for evaluating model-mediated systems rather than treating every task as one completion.
- G-Eval: NLG Evaluation using GPT-4 with Better Human Alignment: studies model-based evaluation for open-ended language generation and reports both alignment potential and bias toward model-generated text.
- Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena: examines LLM judges, reports useful agreement with human preferences, and identifies position, verbosity, self-enhancement, and reasoning limitations.
- Judging the Judges: A Systematic Study of Position Bias in LLM-as-a-Judge: investigates how candidate position can influence model-based judgments and why evaluation protocols need explicit bias testing.
- QuickCheck: A Lightweight Tool for Random Testing of Haskell Programs: foundational property-based testing lineage for checking general properties across many generated inputs rather than only fixed examples.
Subscribe
Get new posts by email
Enterprise architecture, AI systems, and platform strategy.