Agent Memory
Agent memory is not a second context window: it is a governed write, manage, and read path that persists selected state without turning every prior observation into truth.
Agent Memory
When State Started Choosing What to Remember
An agent that forgets everything after one request is not necessarily broken. Statelessness is often the right design for a small, isolated task.
The problem changes when a system works across a long investigation, multiple sessions, a changing environment, or a relationship with a user. It needs to carry something forward. The difficult question is not how to store more text. It is what should persist, under which scope, for how long, with whose authority, and how it should be recalled later.
That is the problem now gathered under the phrase agent memory.
The phrase sounds cognitive. The engineering problem is familiar. It is state management at a new boundary, where a model may help propose what to write, choose what to retrieve, and interpret the result that returns to its context.
This is Post 08 in The Abstraction Shift: How Software Keeps Moving Up.
In One Sentence
Agent memory is a governed write, manage, and read path that persists selected state across model decisions without treating every prior observation, summary, or inference as truth.
The short answer to the roadmap’s question, “Is this really just state?”, is both yes and no.
At the foundation, memory is state. It has a representation, an owner, a lifecycle, a consistency model, an access boundary, and a cost. It can be stored, indexed, versioned, expired, corrected, and deleted.
The difference is that an agent can participate in decisions about the state. The model may extract a candidate fact from a conversation, summarize a task, select a memory to recall, or propose that an old record is no longer useful. Those proposals remain probabilistic. The application still needs to decide what may persist and what may influence an action.
Memory is therefore not a magical second mind and not merely a larger prompt. It is an application-managed state layer whose write and read paths may include model inference.
Why This Exists
A model invocation starts with a context. That context may include the user’s request, instructions, tools, retrieved material, earlier messages, application state, and observations from previous steps. When the invocation ends, the model does not automatically own a reliable, searchable record of what happened.
The application has to carry information across the boundary.
This becomes important in at least four situations:
- Long-running work: a coding, research, or operations task may span multiple context windows and interruptions.
- Multi-session interaction: a user may expect a system to continue a project without replaying every prior exchange.
- Personalization: a system may need stable preferences or constraints, subject to consent and correction.
- Learning within a task: an agent may discover an identifier, failed approach, unresolved dependency, or useful procedure that matters later in the same workflow.
The naive response is to append the entire transcript to every future request. That is expensive, slow, and increasingly noisy. A longer context window does not remove the need for selection. More tokens can make relevant information harder to find and can mix old assumptions with current facts.
The other naive response is to save every model output as memory. That turns guesses into records. A model-generated summary can be useful, but it is not automatically an observed fact. A prior answer can be wrong, stale, out of scope, or based on a source that the current user may not access.
Memory exists because continuity needs a deliberate state boundary. The boundary must preserve enough history to support the next decision while keeping authority, scope, uncertainty, and lifecycle visible.
What We Did Before
Agent memory recomposes several familiar patterns. None of them disappears when a model enters the loop.
Application state
Traditional applications carry state between requests: a shopping cart, a workflow status, a feature flag, a draft, a session identifier, or the current step in a process.
The code usually defines the allowed transitions. A request validates its inputs, applies a state transition, persists the result, and returns an outcome. The next request reads the state through a known interface.
This is the most important lineage. Agent memory is still state with ownership, transitions, persistence, and failure semantics. The new problem is that a model may propose a transition or interpret an unstructured observation before the deterministic state boundary is reached.
Sessions and conversation history
Chat systems already store messages and replay some of them into later requests. Applications may keep a session record, truncate old turns, summarize a conversation, or allow a user to start a new thread.
Conversation history is not the same thing as memory. A transcript records what was said. Memory is a selected representation intended to be useful later. The transcript may be the evidence from which a memory is derived, but the memory should not replace the original record when the distinction matters.
Databases, caches, and indexes
Databases persist records. Caches keep frequently used data close to a consumer. Indexes make records discoverable through a different access path. Materialized views derive a queryable representation from other data.
These distinctions are essential for agent memory. A vector index may make a note easy to retrieve, but it is not the note’s authority. A semantic summary may be a useful view, but it is not a lossless copy of the events from which it was created. A cache may be stale by design.
Calling a vector store a memory system does not answer who owns the data, what the record means, or when it should be removed.
Event logs and workflow checkpoints
Distributed systems record events and checkpoints so work can resume after a failure. A workflow may persist its current step, inputs, outputs, retries, and unresolved dependencies.
This pattern is particularly close to memory for long-running agents. The next process or context window needs a compact, reliable description of what has happened and what remains. The checkpoint is not a personality. It is durable execution state.
The analogy also sets a useful boundary. A checkpoint should be written according to workflow semantics, not only according to what a model finds interesting. If resuming the task depends on an identifier, a pending approval, or an idempotency key, those fields should be explicit and validated.
Profiles, notebooks, and human memory
Applications have long stored user profiles, preferences, CRM notes, bookmarks, and case histories. Humans use notebooks and external records to extend their own working memory.
These patterns explain why selective recall is valuable. They also expose the limits of the human-memory analogy. A person may judge a remembered detail in context and recognize that it has become outdated. A system needs explicit metadata and policy to do the equivalent. It cannot rely on the record feeling familiar.
The composition is new even when the ingredients are old: a model can help decide which state is worth preserving and which state should be loaded for the next decision.
The Abstraction Shift: How Software Keeps Moving Up
The older application pattern is mostly explicit:
event → code-defined transition → persisted state → next request
The agent-memory pattern adds a model-mediated boundary:
observation → memory candidate → write policy → persisted memory → recall policy → context projection → model decision
The model can help extract a preference from a conversation, turn a tool trace into a task checkpoint, search a memory index, and interpret a recalled record. The runtime must still enforce identity, scope, retention, access, validation, and action authority.
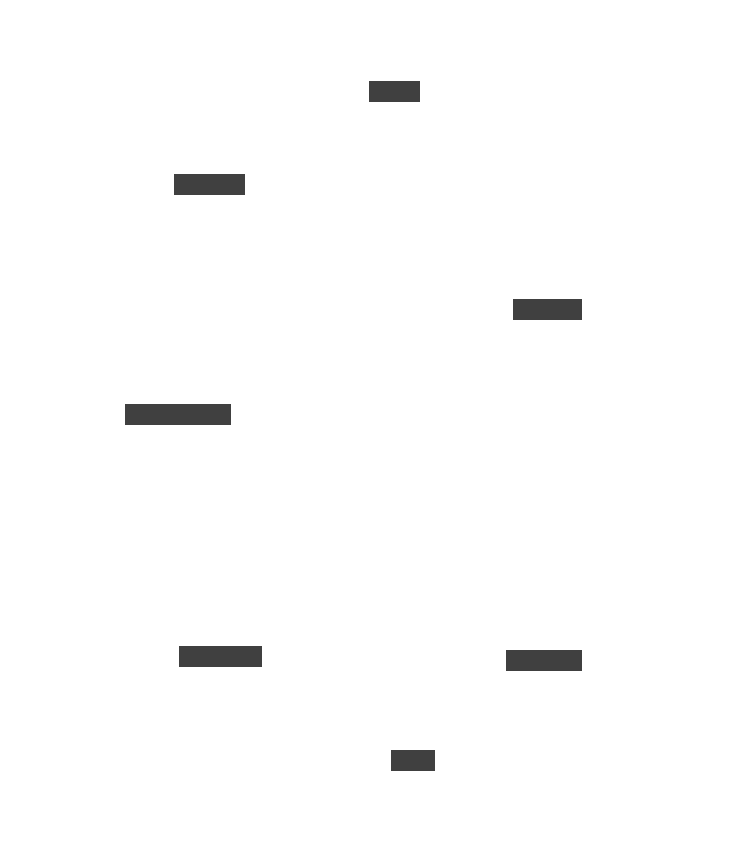
Agent memory is a lifecycle: observe, propose, govern, persist, retrieve, project, and evaluate.
This is not a distinction between a database and a vector database. It is a distinction between a state boundary whose transitions are fully specified by application code and one where a model participates in the interpretation and selection of state.
That participation changes the engineering surface. Memory now has a write path and a read path, and both need evaluation.
The write path asks:
- Was this observation worth persisting?
- Is it a fact, a hypothesis, a preference, a task checkpoint, or a generated interpretation?
- Who or what is the source?
- Which user, tenant, task, or agent may own it?
- How long should it remain valid?
- Does it conflict with an existing record?
The read path asks:
- Which memories are relevant to this task?
- Are they in scope for this identity and purpose?
- Are they current enough to use?
- What authority do they have compared with current system records?
- How much can enter the working context without reducing focus?
The label memory is useful because it puts continuity and recall in view. The durable architecture is the governed state lifecycle beneath the label.
What’s Actually New?
The write operation can begin as a model proposal
Traditional software usually writes a field because a known event and code path say to write it. An agent may encounter unstructured conversation, documents, tool results, and observations that could contain useful future state.
The model is good at proposing a candidate representation from that material. It is not a reliable authority for whether the candidate is true, permitted, durable, or safe to share.
A memory write should therefore have a proposal stage and an acceptance stage. The proposal can include a normalized value, its source, a scope, a reason to retain it, and an expiration suggestion. A deterministic policy or an explicit user action can then accept, reject, redact, limit, or route it for review.
Retrieval becomes semantic and task-dependent
A state lookup often has a known key. Memory retrieval may begin with a natural-language goal: find what this user prefers, recover the last unresolved task, or identify what the previous shift discovered.
Semantic retrieval makes the system flexible, but relevance is not enough. A memory can be relevant and still be stale, unauthorized, speculative, or less authoritative than a current record. Retrieval should combine meaning with structured filters such as identity, tenant, task, time, source, status, and sensitivity.
Memory can influence control flow
A recalled record does not only improve an answer. It can change what the agent does next.
A task checkpoint can cause it to resume at a later step. A remembered failed approach can prevent repeated work. A stored procedure can guide tool selection. A user preference can change the proposed output format. A stale or poisoned memory can redirect the system toward the wrong operation.
That makes memory part of the control loop, not a passive archive. It deserves the same attention as tool calls and retrieval decisions: traceability, limits, authorization, evaluation, and explicit failure states.
Representations become derived and lossy
Memory systems often compress a sequence of observations into a summary or a generalized fact. The resulting record is smaller and easier to recall, but some context is discarded.
The system should distinguish the derived record from the source material. A summary may state that a deployment was suspected during an incident. The original trace may show that the suspicion was later rejected. If the summary survives without its provenance or invalidation, the agent can repeatedly rediscover an old mistake.
Compression is not neutral. It is a state transformation with information loss, so it needs a reason, a version, and a way to recover or regenerate the representation when the source changes.
Memory crosses the session boundary
Session history can often be discarded when a conversation ends. Durable memory cannot be treated as a local implementation detail once it crosses sessions, users, teams, tenants, or products.
The system needs an ownership and retention model. A note useful to one task may be inappropriate for a user’s general profile. An organization procedure may be shareable across a team but not with an external customer. A private preference may not be visible to a support agent or another tenant.
The boundary is architectural because the data can affect future behavior even when the original conversation is no longer visible.
Memory Has Several Useful Lifetimes
The word memory hides different state lifecycles. A practical design starts by naming the lifetime and owner before choosing a storage technology.
| State kind | Typical purpose | Owner and lifetime | Main risk |
|---|---|---|---|
| Working context | Support the current model decision | Runtime, one turn or short loop | Context overload and omission |
| Task state | Resume a workflow or investigation | Workflow, until completion or expiry | Lost progress, duplicate work, wrong resumption |
| Session history | Preserve a conversation or interaction | Application and user, session retention | Unwanted persistence and summary drift |
| Episodic memory | Recall a particular prior event | Agent or application, explicit retention | Stale or misinterpreted event |
| Semantic memory | Reuse a generalized fact or preference | User, team, or domain owner | False inference and scope leakage |
| Procedural memory | Reuse a method, rule, or learned procedure | Application or team, versioned lifecycle | Outdated instructions and hidden policy |
| Authoritative state | Represent current business or system truth | Source system, independent lifecycle | Treating a derived memory as authority |
These categories overlap. A task checkpoint can contain an episodic observation and a semantic conclusion. A conversation summary can be used as session memory and later promoted into a durable preference.
The categories are still useful if they lead to different controls. A current account balance should be read from the account system. A user’s preferred report format may be stored as a durable preference. An incident hypothesis should carry uncertainty and an expiry. A task checkpoint should preserve exact identifiers and operation status.
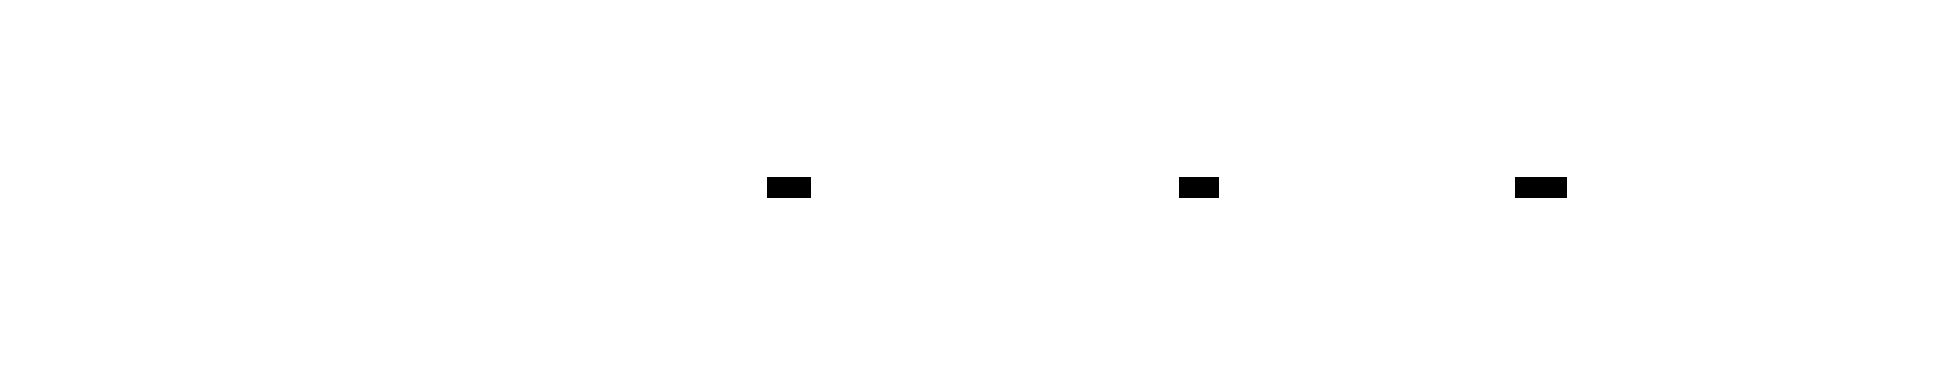
Working context, task state, session history, durable memory, and system records have different owners and lifetimes.
Where the Analogy Breaks
Memory is not model learning
Updating an external memory record does not update the model’s parameters. The model may appear to learn because the application retrieves the record in a later context, but the behavior depends on the memory store, retrieval path, and context assembly.
This distinction matters operationally. External memory can usually be inspected, corrected, scoped, expired, or deleted without retraining the model. It can also fail independently of the model through indexing errors, stale records, access bugs, and retrieval misses.
Recall is not truth
A memory that ranks highly for a query is not necessarily correct. Relevance, authority, freshness, and confidence are different properties.
The model should see enough metadata to distinguish an authoritative current record from a model-generated hypothesis. The runtime should not let a recalled sentence silently override the system that owns the underlying fact.
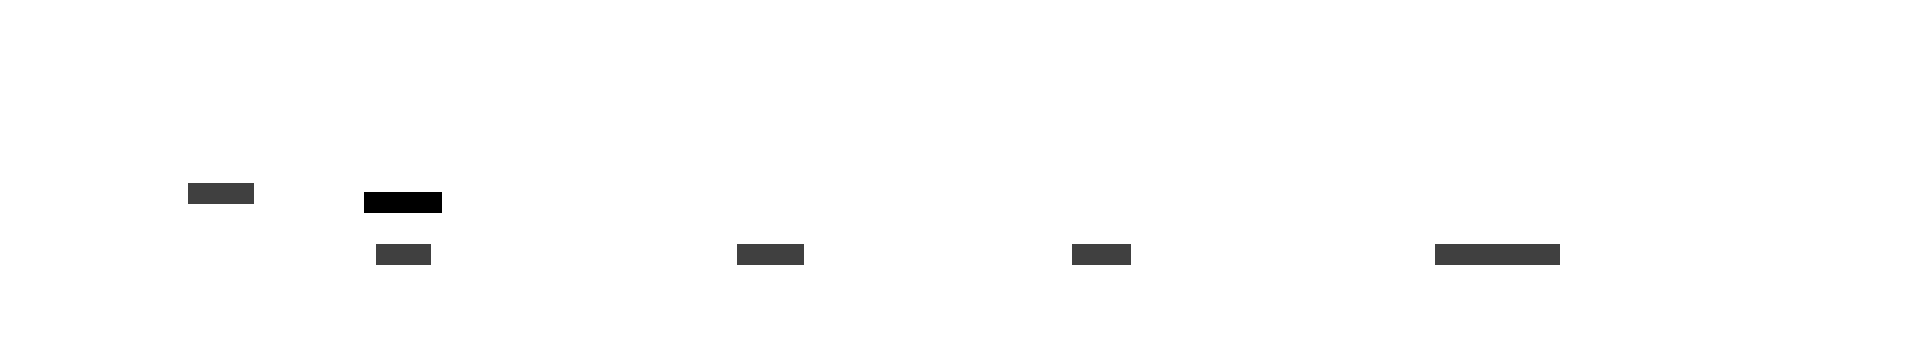
Persisted memory may help a model decide, but it does not become authoritative merely because it was recalled.
A summary is not a transcript
Summarization removes detail. It may preserve the conclusion while losing the conditions under which that conclusion was reached. It may collapse a disagreement into one sentence or omit the fact that a proposal was never executed.
Summaries should link to their source, record their creation time, retain important uncertainty, and be replaceable. For consequential decisions, the original evidence should remain available for inspection.
Forgetting is not just deletion
Deleting a row from a memory table may not remove a copy from an event log, an embedding index, a cache, a backup, a transcript, a derived summary, or a downstream export.
The right deletion behavior depends on the data lifecycle and legal or product requirement. The system needs to know which representations exist and how a correction or deletion propagates. “Forget this” is a workflow across storage layers, not a prompt instruction.
The model is not the owner of personal meaning
A model may infer that a user is anxious, financially constrained, or likely to prefer a certain outcome. That does not make the inference appropriate to store. Sensitive traits and consequential judgments require explicit product and governance decisions, and often should not be inferred or retained at all.
The system should prefer explicit user preferences and authoritative domain records over speculative personality models. Personalization is a product boundary with privacy consequences, not a reward for a more human-like agent.
Retrieved memory can become a persistent attack surface
If untrusted content can cause the agent to write a durable note, an attacker may plant instructions or false facts that influence later sessions. A memory write can turn a temporary prompt-injection attempt into a persistent one.
Memory content must be treated as data with provenance and scope. The application should not let a document silently grant permission, alter policy, or write a trusted instruction merely because a model extracted it.
Under the Hood
A production memory path can be decomposed into explicit responsibilities.
1. Define the scope
Bind every memory operation to an identity, tenant, task, session, purpose, and sensitivity policy where relevant. A memory without a scope is an invitation to leakage.
The scope should answer who may write, who may read, which future tasks may use the record, and whether the record can be shared across agents or products. Connection identity is not enough. The application needs an explicit scope that survives retries and process changes.
2. Capture an observation
Collect the source event, message, tool result, record reference, or workflow outcome. Keep the raw observation separate from any model interpretation.
A useful trace records when the observation was made, which source produced it, what authorization applied, and whether the operation actually succeeded. This prevents the memory layer from confusing an attempted action with a completed action.
3. Propose a candidate
The model or deterministic code can propose a normalized memory candidate. The candidate should name its kind, content, source, intended scope, reason to retain it, and suggested validity period.
The candidate should be allowed to remain a candidate. Not every observation deserves a write, and not every write should be accepted automatically.
4. Apply the write gate
The write gate checks schema, authorization, sensitivity, consent, retention, size, duplication, and conflict rules. It may require explicit user confirmation, a domain owner, or a human reviewer.
For a user preference, the product may ask the user to confirm it. For a task checkpoint, the workflow may accept a structured record automatically. For an inferred medical, financial, or employment characteristic, the policy may reject persistence entirely.
5. Persist and index
Store the accepted record with an identifier, version, provenance, timestamps, scope, status, and deletion or expiry metadata. Create retrieval indexes as derived views.
The storage design should support correction and supersession. An old memory should not remain equally eligible after a newer authoritative record replaces it. Index refresh is part of correctness, not only a performance concern.
6. Retrieve for a purpose
Memory retrieval should be tied to the task at hand. Combine semantic similarity with structured constraints. Prefer a small, high-signal result over a large memory dump.
The retrieval result should expose enough metadata for the next decision: source, age, authority, scope, status, confidence or uncertainty, and links to supporting records. A record that cannot explain where it came from is a weak candidate for consequential context.
7. Project into context
The memory store is not the model context. The runtime selects a working set and labels the role of each item. It can include a memory reference, a short value, a source link, and instructions to verify current facts before acting.
This is where Article 06’s context-engineering principle applies. Context is a projection of larger state for one decision. It should not be mistaken for the complete state or for permission to act.
8. Evaluate the loop
Test both memory operations and downstream behavior. A system can write plausible memories and still fail because it never recalls them. It can recall the right item and still fail because the item is stale or causes an unsafe action.
Useful measures include write precision, write recall for required facts, retrieval recall, stale-memory suppression, conflict handling, cross-scope isolation, deletion effectiveness, latency, cost, and the quality of the final task outcome.
A Concrete Example
Consider an internal incident assistant that works across several engineering shifts. A first session investigates a checkout latency regression. The assistant searches incidents, follows a deployment identifier, inspects traces, and records a working hypothesis. The task is paused overnight.
The next shift asks:
What do we know, what remains unverified, and what should I check next?
A transcript replay is a poor interface. It includes every query, repeated tool output, abandoned hypothesis, and model explanation. A useful task checkpoint is smaller and more explicit:
- the original incident scope and time window;
- the deployment identifier that was inspected;
- the evidence that overlaps the incident window;
- the current hypothesis and its status, such as
unverified; - the checks already performed;
- the unresolved conflict between two ownership records;
- the next recommended read-only query;
- the time the checkpoint expires or must be revalidated.
The memory is not allowed to state that the deployment caused the incident unless the evidence and application rules support that conclusion. It should say that the deployment is a hypothesis, preserve the trace references, and prompt the next shift to verify the relevant trace and ownership record.
Now consider a different memory: a customer explicitly asks that future invoices be sent monthly. The system may store that preference under the customer’s account scope, with a source reference, consent record, and a product-defined lifecycle. It should not infer and persist that the customer dislikes a particular payment method because the tone of one conversation suggested frustration.
The same storage technology could hold both records. Their semantics and controls are different. One is task-scoped operational state with a short validity period. The other is an explicit domain preference owned by a customer record. Calling both “memory” is acceptable only if the system preserves that distinction.
What Changes Because of It?
Architecture
Memory becomes a boundary between observations, authoritative records, derived representations, and model-facing context. A useful architecture keeps these layers distinguishable:
- Source systems: own current facts, policies, and business state.
- Event and trace records: preserve what was observed, proposed, attempted, and completed.
- Memory store: holds accepted, scoped, derived records intended for future use.
- Indexes: make memory discoverable through semantic and structured queries.
- Context projection: selects and labels what enters one model decision.
- Policy and execution: decide what may be read, written, authorized, and acted upon.
The memory store should not become a shadow system of record by accident. If every downstream consumer trusts its summaries more than the source system, the architecture has created an ungoverned authority layer.
Engineering
The write path and read path need contracts. Fields such as kind, scope, source, observed_at, valid_until, status, version, and sensitivity are not decorative metadata. They are what lets the system decide whether a memory should be used.
Engineers also need to handle concurrency and correction. Two sessions may write contradictory preferences. Two agents may update the same task checkpoint. A retry may create duplicate records. An index may lag the source store. A memory service needs idempotency, version checks, conflict semantics, and observability.
Testing must include traces rather than only final prompts. Create cases for stale facts, conflicting sources, unauthorized recall, deletion, prompt injection, interrupted tasks, duplicate writes, and a model that confidently proposes the wrong memory.
Product and UX
If memory changes future behavior, users need a meaningful way to understand and control it. The interface may need to show:
- what the system remembered;
- where it came from;
- which scope and purpose apply;
- when it will expire;
- how to correct or delete it;
- why it was used in the current response.
The right interaction is not always a memory dashboard. A confirmation at the moment a durable preference is created may be clearer than a hidden settings page. The product should also distinguish conversation history, saved preferences, task progress, and authoritative account data.
Business and operations
Persistent memory creates retention, privacy, security, support, and cost obligations. The longer a system retains a record, the more opportunities exist for it to become stale, exposed, or inconsistent with a changed relationship.
Operations teams need to observe memory writes, recall decisions, deletion propagation, index health, stale-record rates, and the cost of repeated retrieval. Support teams need a way to explain and repair surprising behavior. Governance teams need to know which representations contain personal or regulated data and which agents or products can access them.
The memory feature is not complete when the model can recall a previous detail. It is complete when the organization can operate that detail as data.
Failure Modes
False memory
The model converts an assumption, hallucination, or ambiguous statement into a durable fact. Require provenance, candidate status, explicit user confirmation, or a domain-owner check for higher-risk records.
Stale memory
A once-correct preference, procedure, or incident hypothesis remains eligible after the world changes. Add validity periods, freshness checks, supersession, and authoritative revalidation.
Scope leakage
A memory created for one user, tenant, task, or purpose appears in another context. Enforce scope at write, storage, index, retrieval, and context-assembly boundaries. Do not rely on the model to respect a label it can misread.
Memory poisoning
Untrusted content causes the agent to persist a malicious instruction or false fact. Separate data from instructions, restrict write permissions, record provenance, and require stronger gates for durable procedural memory.
Summary drift
Repeated compaction and rewriting gradually change the meaning of an event. Keep source links, versions, uncertainty, and a regeneration path. Do not treat a summary as a lossless record.
Authority collision
A derived memory conflicts with a current source system, but the model selects the more fluent or recent-looking sentence. Make ownership and precedence explicit, then validate consequential claims outside the model.
Inferred identity or sensitive traits
The system stores a judgment about a person that was never explicitly provided or authorized. Prefer explicit preferences and domain-owned records, and reject sensitive inferences that do not have a legitimate purpose and control path.
Write amplification
Every turn, tool result, and intermediate thought becomes a record. Storage, indexing, retrieval latency, and review costs grow while signal quality falls. Use write budgets, deduplication, candidate thresholds, and task-specific schemas.
Recall flooding
The system retrieves too many memories and fills the working context with old material. Use a small working set, purpose-bound retrieval, age and authority filters, and explicit omission traces.
Broken forgetting
The visible memory is deleted but a summary, index entry, cache, backup, or downstream export still returns it. Model the full representation graph and test deletion as an end-to-end lifecycle.
Hidden dependency on memory
A workflow works only because an undocumented memory happens to be recalled. The task cannot be reproduced, audited, or resumed when retrieval changes. Make required state explicit in the workflow contract and keep memory as a traceable input.
KNOW / UNDERSTAND / BUILD
KNOW
Know that agent memory is external state used to support future model decisions. Know the difference between working context, conversation history, task checkpoints, durable memory, retrieval indexes, model weights, and authoritative system records.
Know that a model can propose what to remember and what to retrieve, but the application owns scope, validation, authorization, retention, deletion, and action authority.
UNDERSTAND
Understand memory as a write, manage, and read lifecycle. Be able to explain why a memory record needs provenance, scope, time, authority, status, and a path for correction.
Understand the distinction between a source of truth, an event log, a derived memory, an index, and a model-facing context projection. Be able to identify where a stale, false, or poisoned memory can change control flow.
BUILD
Build a small task-memory experiment for a multi-step investigation. Compare:
- replaying the full transcript;
- compacting the transcript into one summary;
- storing structured task state with provenance, status, scope, and expiry;
- retrieving a small context projection for the next step.
Measure task completion, retrieval precision, stale-memory suppression, recovery after interruption, token use, latency, cost, cross-scope isolation, and deletion behavior. Include cases where the model proposes a false memory and where two sources conflict.
Recommended depth: UNDERSTAND
Build It Once
Start with a structured record and an explicit acceptance boundary. A minimal task-memory entry might look like this:
{
  "id": "memory-042",
  "scope": {
    "tenant": "acme",
    "task": "incident-checkout-2026-09-12"
  },
  "kind": "task_checkpoint",
  "content": "Deployment deploy-1842 overlaps the incident window; causality remains unverified.",
  "source": {
    "type": "trace_observation",
    "ref": "trace/incident-checkout/step-4",
    "observed_at": "2026-09-12T14:00:00Z"
  },
  "status": "accepted",
  "authority": "derived",
  "valid_until": "2026-09-13T14:00:00Z",
  "version": 1
}
Then implement four separate operations:
propose_memory, which produces a candidate from an observation;accept_memory, which applies deterministic policy and records the decision;retrieve_memory, which filters by scope, purpose, status, authority, and freshness;project_context, which selects a small model-facing working set with provenance.
Keep the original observation and the model proposal in the trace. Make acceptance, rejection, correction, supersession, expiry, and deletion visible events. If the system cannot tell the user why a memory appeared, it is not ready to make that memory part of a consequential decision.
This small design teaches the durable boundary. The model can help interpret experience. The runtime decides which interpretation becomes state, who may see it, how long it remains valid, and whether it can influence an action.
Will This Term Survive?
Terminology durability: medium.
Agent memory is a useful phrase because it names a current design concern, but it groups together several different lifecycles: task state, session history, episodic records, semantic preferences, procedural knowledge, and context compaction. The exact taxonomy will continue to change.
The phrase may give way to long-term memory, persistent context, memory systems, stateful agents, durable agent state, or more specific names for each store and lifecycle. The human analogy will remain attractive, but it should not replace the data model.
Pattern durability: high.
Long-lived software needs state, persistence, checkpoints, caches, indexes, provenance, access control, retention, correction, and deletion. Those responsibilities do not disappear when a model participates in writing or reading the state.
The durable formulation is:
Agent memory is application-managed state optimized for future model decisions, with model participation in the write and read paths.
The model may decide what seems useful. The system must decide what is allowed, what is true enough for the purpose, and what can affect the world.
Where It Fits in the Map
Agent memory connects the AI-native control loop to the durable software-engineering problem of state:
- Post 02, Agent and Agent Design Patterns: an agent needs state to carry goals, observations, budgets, and progress across a control loop. Memory is a cross-cutting capability, not a separate agent species.
- Post 03, The Application Boundary Is Weakening: memory can be shared across experiences and consumers, so ownership, identity, authority, and scope must remain visible as the application boundary opens.
- Post 04, Tool Calling: memory operations are capabilities with contracts. A model may propose a write or recall, but the runtime validates the arguments and enforces permission.
- Post 05, Model Context Protocol: a protocol can expose memory tools or resources, but protocol compatibility does not establish authority, retention, privacy, or truth.
- Post 06, Context Engineering: memory is one source from which a context projection is assembled. The projection is not the full state and not a source of truth.
- Post 07, RAG to Agentic RAG: retrieval can navigate external evidence, while memory carries selected state across steps and sessions. Both need provenance, scope, freshness, and bounded context.
- Future durable execution and security topics: long-running work, prompt injection, evals, observability, approval, and deletion extend the same state lifecycle.
The abstraction shift is from state that application code carries explicitly to state whose selection and interpretation may be model-mediated. The engineering answer is not to pretend that the model has human memory. It is to make the state boundary more explicit: what was observed, what was proposed, what was accepted, what is authoritative, what may be recalled, and what must be forgotten.
Sources
- MemGPT: Towards LLMs as Operating Systems: an OS-inspired approach to virtual context management, memory tiers, and control flow across limited context windows.
- Generative Agents: Interactive Simulacra of Human Behavior: an influential architecture combining experience records, reflection, and dynamic retrieval for behavior over time.
- A Survey on the Memory Mechanism of Large Language Model based Agents: a review of memory mechanisms, applications, and evaluation questions for LLM-based agents.
- Memory for Autonomous LLM Agents: Mechanisms, Evaluation, and Emerging Frontiers: a recent survey framing agent memory around write, management, read, evaluation, privacy, and long-horizon operation.
- Effective context engineering for AI agents, Anthropic: context limits, compaction, structured note-taking, and persisted notes as one technique for long-horizon work.
- Effective harnesses for long-running agents, Anthropic: long-running work across discrete sessions and the need for explicit continuity between them.
- Building effective agents, Anthropic: workflows, agents, tools, memory, and the recommendation to use the simplest sufficient architecture.
Subscribe
Get new posts by email
Enterprise architecture, AI systems, and platform strategy.