RAG to Agentic RAG
RAG adds external evidence to generation; agentic RAG makes search, inspection, and stopping decisions part of a bounded control loop.
RAG to Agentic RAG
When Retrieval Became Part of the Control Loop
Retrieval-augmented generation solved an important problem: a model does not have to rely only on what is stored in its parameters. The application can find relevant external material and place it beside the request before generation.
That pattern is powerful, but many questions do not have one clean retrieval step. The query may be ambiguous. The relevant source may not be known in advance. One document may reveal the identifier needed to find the next document. A first result may answer one part of the question while exposing a conflict or an unanswered dependency.
This is where the phrase agentic RAG has appeared. The phrase is used inconsistently, but its useful meaning is clear enough: retrieval becomes part of a model-assisted control loop. The system can formulate a search, inspect the result, update its evidence state, decide what to retrieve next, and stop when it has enough support for the requested outcome.
The durable change is not that a model is allowed to search. Search systems have always supported query expansion, faceting, federation, relevance feedback, and iterative human research. The change is that retrieval can now become one of the actions selected inside a probabilistic decision loop, with the model helping decide what to ask for next.
This is Post 07 in The Abstraction Shift: How Software Keeps Moving Up.
In One Sentence
RAG retrieves evidence before generation, while agentic RAG treats retrieval, inspection, refinement, and stopping as a bounded control loop whose state includes the evidence gathered so far.
The distinction is about control flow, not branding.
Traditional application RAG often follows this shape:
user question → retriever → selected chunks → model → answer
Agentic RAG may follow this shape:
goal → query or source choice → retrieval → inspection → evidence update → next query or synthesis
The second shape is not automatically better. It adds latency, cost, nondeterminism, and more failure modes. It is useful when the task requires exploration, multiple sources, query reformulation, multi-hop reasoning, or explicit evidence gathering that a fixed retrieval pass cannot provide reliably.
Why This Exists
A model’s parameters provide a kind of learned, implicit memory. That memory is broad but difficult to update precisely, inspect, or constrain to one organization’s current facts. Retrieval adds a non-parametric memory that the application can update and inspect.
The original RAG paper described a system that combines a pretrained generator with a dense vector index accessed by a neural retriever. The application pattern that most engineers now call RAG is usually more operational: split documents into chunks, index them, retrieve a limited set for a request, and add them to the model’s context before generation.
That pipeline works well when the question, corpus, and retrieval task are sufficiently clear. It becomes strained when the question is really a small investigation:
- Which service owns this behavior?
- What changed before the incident?
- Which policy applies to this customer and date?
- Does the contract exception override the default rule?
- What evidence supports the recommendation, and what remains unknown?
These questions contain dependencies. The answer to one retrieval step changes the terms, source, scope, or time range of the next step.
An ordinary search interface lets a human perform that loop. A fixed RAG pipeline hides the loop in application code or leaves it to one model call. Agentic RAG makes the loop explicit and allows the model to participate in selecting the next retrieval operation.
The system still needs deterministic boundaries. The model can propose a query or select a read-only source. The retrieval service should enforce identity, scope, rate, result limits, and source policy. The evidence layer should preserve provenance and freshness. The application should decide whether the final evidence is sufficient for the requested use.
What We Did Before
The ingredients of agentic retrieval are not new. The composition is.
Information retrieval
Search engines have long ranked documents against queries using lexical matching, links, learned relevance, facets, filters, and user feedback. Query expansion and relevance feedback let one search result improve the next query.
The durable lesson is that retrieval quality is its own engineering discipline. A language model does not remove the need for indexing, segmentation, ranking, evaluation, access control, and freshness.
Database access
Applications routinely retrieve data in stages. A user identifier leads to an account record. The account record leads to orders. An order leads to shipment events. Each query is shaped by the previous result.
This is a useful analogy for multi-hop retrieval because it emphasizes typed identifiers, scope, joins, and constraints. It breaks when the model is asked to infer the next query from loosely structured natural language without the guarantees of a query planner or schema checker.
Federated search
Enterprise search systems query multiple indexes and normalize the results into one experience. They may search tickets, documents, code, policies, and operational records together.
Agentic RAG can add model-directed source selection to that design. But the underlying services still need to identify their data owner, access rules, result semantics, and failure states. Federation does not turn incompatible sources into one trustworthy corpus.
Human research
A researcher starts with a question, searches for likely sources, reads enough to refine the question, follows references, compares conflicting evidence, and decides when the result is strong enough to report.
This is the closest analogy. It explains why agentic retrieval is attractive for open-ended investigation. It also explains the central risk: a researcher can become anchored to the first plausible explanation, mistake a confident source for an authoritative one, or continue searching long after the value of another query is lower than its cost.
Workflow orchestration
A workflow can already implement retrieval steps in code. Search the catalog, fetch records, apply filters, call an evaluator, and route the result to a human.
Agentic RAG is not a reason to replace every workflow with a model. A fixed workflow is often preferable when the source sequence, data shape, and stopping rule are known. The model belongs in the loop when the problem requires flexible query or source selection and the surrounding system can tolerate and control that flexibility.
The Abstraction Shift: How Software Keeps Moving Up
The important shift is from retrieval as a preprocessing stage to retrieval as a runtime capability.
In a conventional RAG pipeline, the retriever is usually invoked once for the current request. Its output becomes context, and the generator produces an answer. In an agentic system, a retrieval result is an observation. It may answer the question, reveal a new identifier, contradict another source, or show that the original query was poorly framed.
That observation changes the next action.
fixed RAG:
  request -> retrieve -> augment -> generate

agentic RAG:
  goal -> search -> inspect -> update evidence
           ^                    |
           |------ refine ------|
                         |
                      synthesize
The application therefore needs more than a retriever and a prompt template. It needs a control loop with a working state, capability boundaries, budgets, observation semantics, and an evaluation strategy.
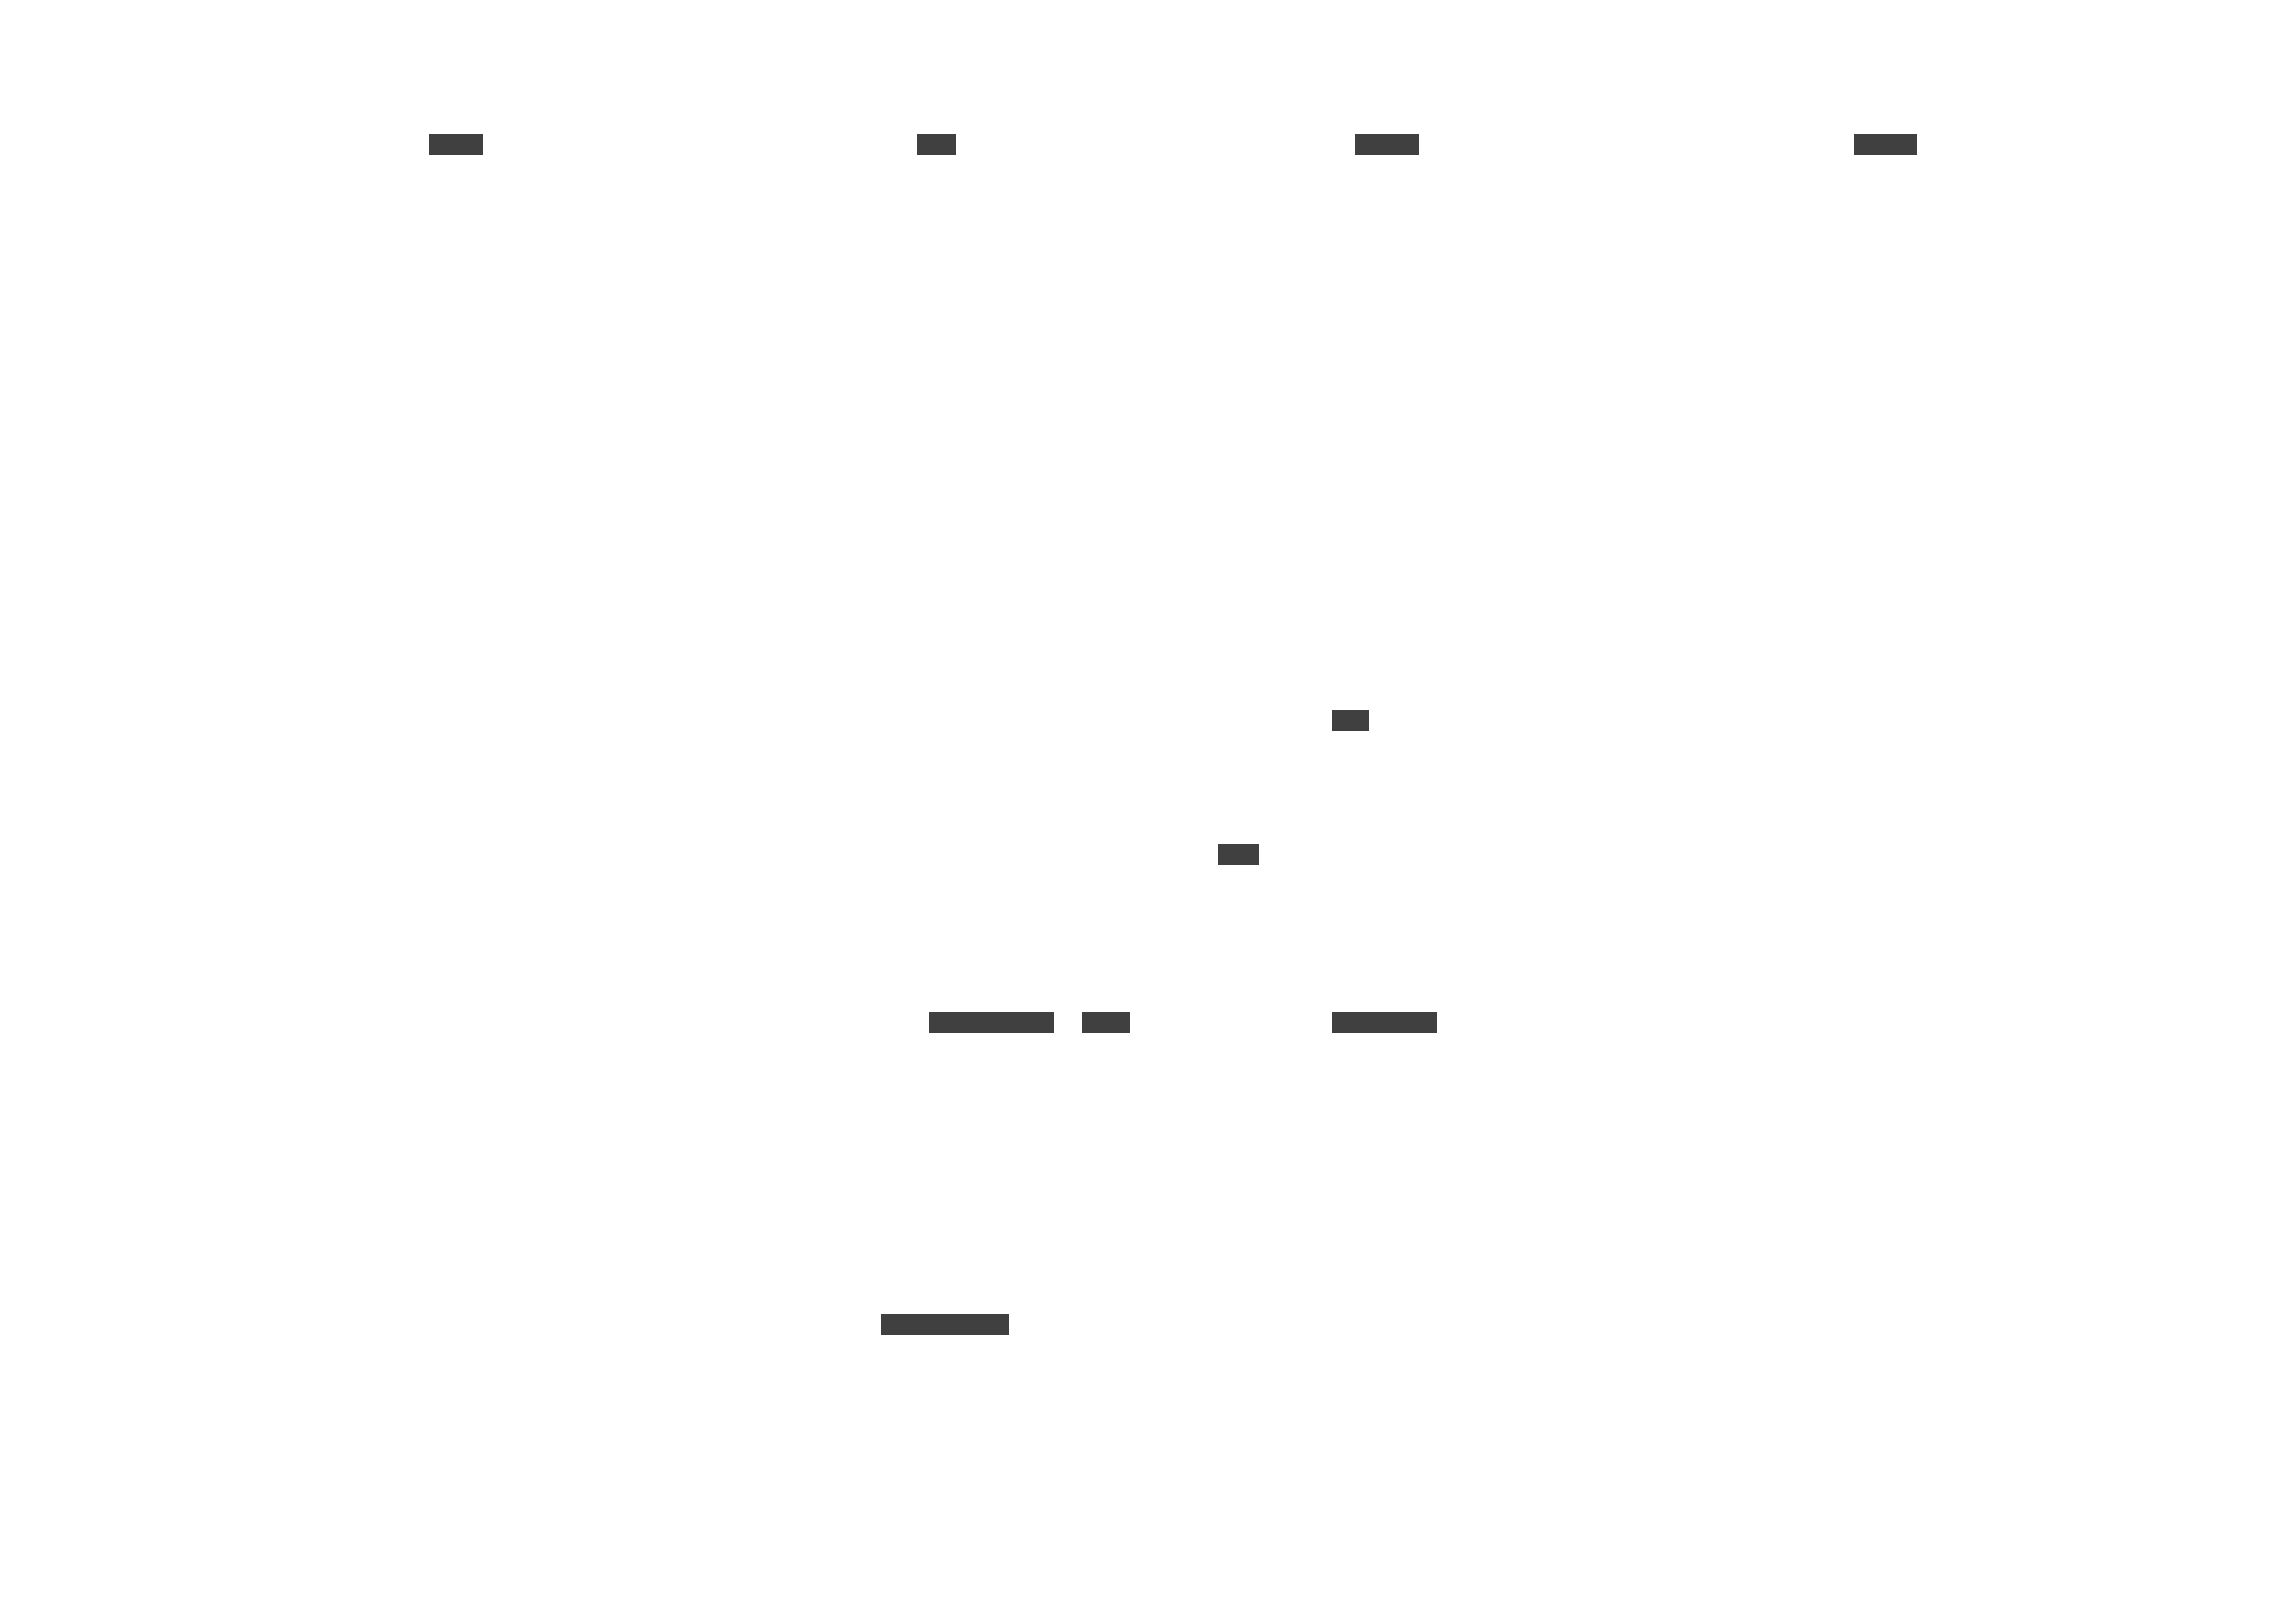
The shift from RAG to agentic RAG is a shift from one retrieval pass before generation to retrieval as part of an adaptive control loop.
The term agentic RAG should not be used for every improvement to a retrieval pipeline. Hybrid search, contextualized chunks, reranking, query rewriting, and multiple retrieval calls can improve a RAG system without making it agentic. The useful question is whether the system can dynamically choose and sequence retrieval actions based on observations during the task.
What’s Actually New?
Retrieval becomes a selected action
In a fixed pipeline, application code decides when to retrieve and often fixes the query shape. In an agentic loop, the model may propose a search query, choose between a document search and a structured database lookup, or request the next page of a result.
That creates flexibility, but it also makes search a capability boundary. A retrieval tool needs a clear purpose, explicit inputs, bounded results, and a response that contains enough meaning for the next decision without dumping the entire source object into context.
The tool should not expose an unrestricted search over every system the user might theoretically access. The host and runtime should decide which sources are available for the task, and the source system should enforce authorization again.
Evidence becomes state
A list of retrieved chunks is not an evidence model. The system needs to know which claim each item supports, what source and scope it belongs to, when it was observed, whether another source conflicts with it, and whether it is authoritative for the decision.
Without that state, each new model turn receives a growing pile of text. The model may repeat a claim, lose the relationship between a source and a fact, or treat an earlier hypothesis as a confirmed result.
An evidence state can remain lightweight. It might contain claims, citations, identifiers, source metadata, open questions, conflicts, and a confidence or review status. The point is not to make the model produce a perfect knowledge graph. The point is to keep the system from confusing retrieved material with validated knowledge.
Stopping becomes part of retrieval
A fixed RAG request has an obvious stop: retrieve the configured number of chunks and generate. An agentic loop needs a stopping rule.
The system may stop when the answer is supported by sufficient independent evidence, when the required sources have been checked, when the question is outside scope, when the budget is exhausted, or when a human must resolve a conflict. “The model sounds confident” is not a sufficient stopping rule.
Stopping criteria should be partly deterministic. Maximum steps, token budget, time budget, source allowlists, rate limits, and escalation conditions belong outside the model. The model can estimate whether more evidence would help, but it should not control an unbounded search process.
Context can be loaded just in time
Article 06 described context engineering as the management of the model’s working set. Agentic retrieval gives that idea an important operating pattern: keep lightweight references in state and load the underlying material only when the next decision requires it.
A system can carry a document identifier, search result pointer, query, or source link rather than repeatedly copying an entire document into the model context. A later tool call can fetch the relevant range, page, record, or surrounding section.
This resembles filesystems, databases, and human research notebooks. The analogy breaks if references are treated as truth. An identifier is a way to find a source. It is not proof that the source is current, authorized, relevant, or safe to follow.
Where the Analogy Breaks
The model is not a query planner
A database optimizer can use a schema, statistics, indexes, and declared constraints to choose among query plans. A model can generate a useful query from a natural-language goal, but it can also invent a field, omit a filter, confuse two identifiers, or choose a source because its description sounded plausible.
Generated queries need syntax checks, parameter validation, authorization, scope limits, and result budgets. Structured tools can reduce ambiguity, but a schema does not validate whether the requested business meaning is correct.
More retrieval can reinforce the first mistake
If the first query encodes a wrong assumption, subsequent queries may search for evidence that supports it. The system can become more detailed without becoming more correct.
The loop needs opportunities to challenge its current explanation: alternative queries, independent sources, contradiction checks, explicit unknowns, and evaluation cases where the obvious first result is incomplete.
Retrieved content can influence control flow
A document, web page, ticket, or tool response may contain text that looks like an instruction. Once it enters context, it can influence the next query or action. This is an indirect prompt-injection problem, not merely a relevance problem.
Retrieved content should be treated as data to consider, not instructions to obey. The runtime should limit what the model can access and do even if the content manipulates its next proposal. Read-only retrieval is a smaller risk surface than retrieval connected directly to external actions, but it is not risk-free.
Evidence sources have different authority
A current operational event, an old runbook, a user-provided note, a generated summary, and a signed policy document may all be relevant to one question. They do not have the same authority.
The system needs source ownership, scope, timestamp, freshness, and conflict semantics. A model should not be left to infer the hierarchy from prose alone, especially when the result could drive a decision with legal, financial, safety, or operational consequences.
The loop has economics
Every extra query consumes tokens, compute, network calls, provider capacity, and user time. A loop that improves recall while multiplying latency may be worse for the product. An agentic design must make the value of another retrieval step visible enough to evaluate against its cost.
Under the Hood
A useful agentic retrieval design separates the following responsibilities:
- Frame the goal. Capture the question, audience, task scope, time range, identity, risk, and required outcome.
- Select the available sources. Choose which indexes, databases, tools, or documents can participate. Apply authorization and data-sharing policy before the model sees the choices.
- Form a query or source request. Let the model propose a query or choose among structured retrieval capabilities, then validate the request deterministically.
- Retrieve a bounded result. Enforce filters, pagination, maximum result size, timeout, rate limit, and redaction. Return high-signal metadata with the content.
- Inspect the observation. Determine whether the result is relevant, complete, current, authoritative, conflicting, or evidence of a new dependency.
- Update evidence state. Record claims, citations, identifiers, open questions, conflicts, and the provenance of each selected item.
- Continue or stop. Apply budget and policy rules, then decide whether another retrieval action would improve the requested outcome.
- Synthesize with uncertainty. Produce an answer or report that distinguishes supported claims, assumptions, conflicts, and unresolved questions.
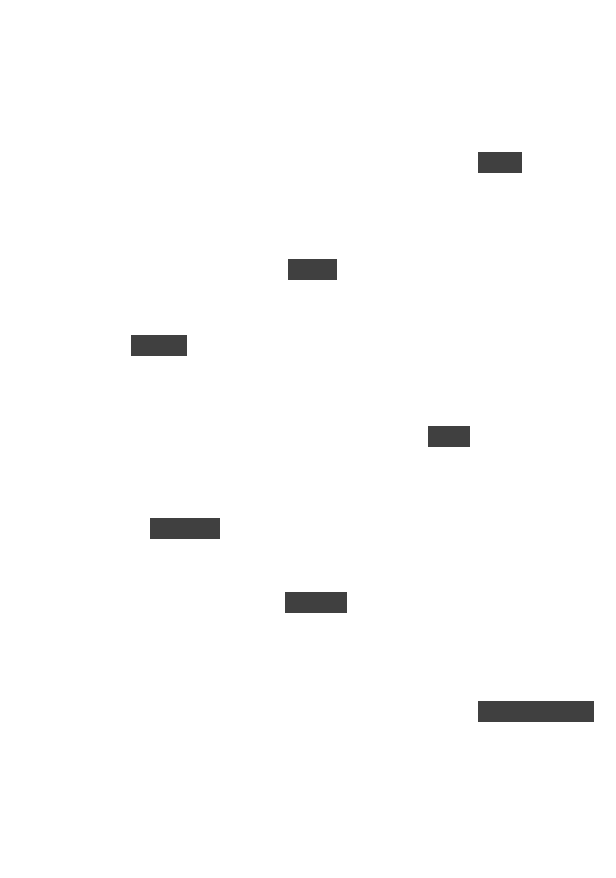
A useful retrieval loop carries evidence state and makes its continuation decision explicit.
This architecture can be implemented with direct model calls, a workflow engine, an agent runtime, or a combination. The implementation choice is less durable than the responsibilities. The system must make it possible to inspect what the model asked for, what it received, what it retained, why it continued, and why it stopped.
A Concrete Example
Consider an internal assistant investigating a checkout latency regression. The user asks:
What changed, which component owns the regression, and what evidence supports that conclusion?
A conventional RAG implementation might embed the question, retrieve the top five chunks from an engineering knowledge base, and ask the model to summarize them. The result may include a general checkout runbook, an old incident report, and a recent performance note. It may sound plausible while missing the deployment that introduced the regression.
An agentic retrieval design begins by framing the task as a read-only investigation with a service, environment, and incident window. It searches the incident index and finds a deployment identifier. That identifier becomes the next query into the deployment system. The deployment record points to a service component and commit. The assistant then retrieves the relevant trace summary, ownership record, and current runbook section.
At each step, the evidence state records the source, scope, observed time, claim, and relationship to the working hypothesis. If the deployment time does not overlap the incident, the loop should weaken or discard that hypothesis. If the ownership record conflicts with the runbook, the result should preserve the conflict rather than silently selecting the more fluent sentence.
The loop can stop when the evidence covers the requested change, owner, and supporting observations, subject to the application’s evaluation rules. It can also stop with explicit uncertainty when the records are incomplete or contradictory. It should not page the on-call team, change a deployment, or close the incident merely because retrieval produced a convincing narrative.
The same pattern applies to a compliance review, a customer-support investigation, due diligence, or a technical architecture question. The sources and schemas change. The need for scoped queries, evidence state, provenance, budgets, and stopping criteria remains.
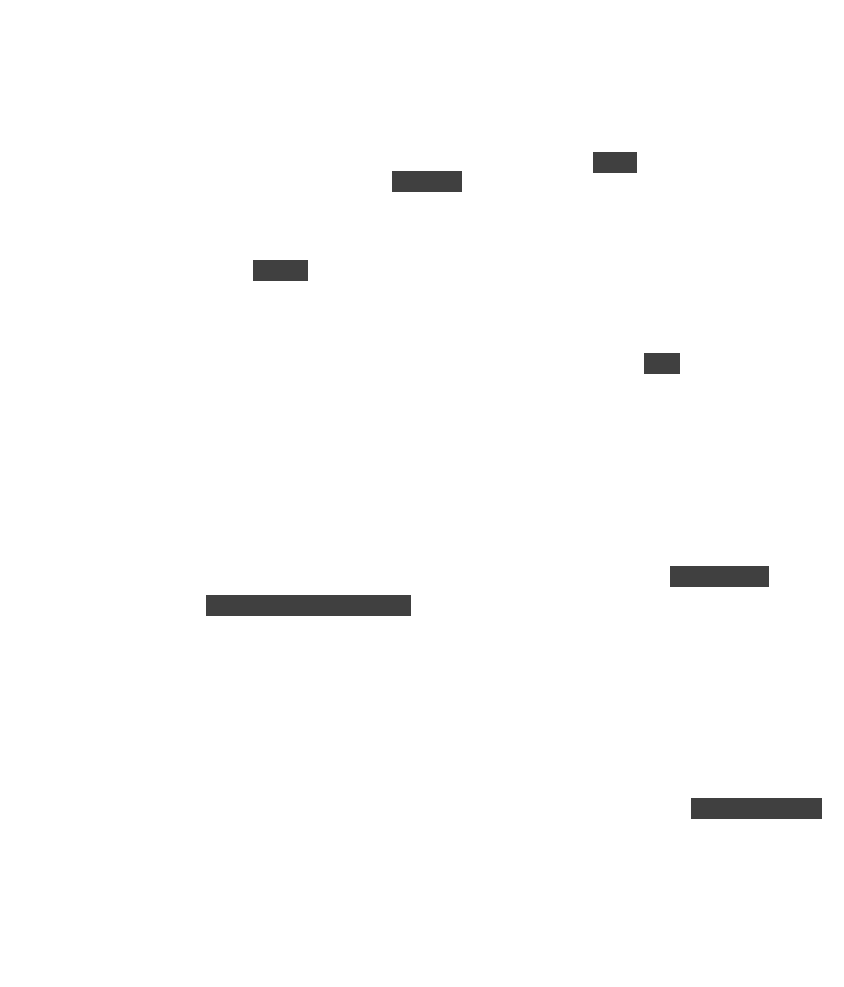
Agentic retrieval should preserve a structured evidence state rather than treating every retrieved passage as undifferentiated context.
What Changes Because of It?
Retrieval becomes an application capability
The retrieval layer is no longer only an offline indexing pipeline. It becomes a runtime capability with a contract, permissions, latency, errors, pagination, observability, and versioned behavior.
Tool design becomes retrieval design
The model may choose among search tools, database lookups, document fetches, source-specific filters, and evidence operations. Tool names, descriptions, input schemas, result formats, and response sizes influence the quality of the loop.
The best retrieval tool is not necessarily the most general one. A small search capability that makes scope, time range, and source type explicit may be easier to select and safer to operate than a single tool that exposes an entire enterprise search surface.
Evaluation must include the path
A final answer can be correct for the wrong reason, or incorrect despite a reasonable retrieval path. Evaluation should therefore inspect both outcome and process:
- Did the system retrieve the authoritative source?
- Did it use the right scope and time range?
- Did it discover the dependency that required a second query?
- Did it preserve or expose conflicting evidence?
- Did it stop within the budget?
- Did it distinguish evidence from inference?
- Did the final answer cite the material that actually supports its claims?
Observability must capture evidence transitions
Request logs are insufficient for a multi-step retrieval loop. A useful trace records the goal, available sources, proposed queries, validated requests, result summaries, selected evidence, omitted evidence, context versions, model proposals, stop reasons, and final outcome.
This trace is valuable for debugging, quality evaluation, security review, cost analysis, and user trust. It also makes the retrieval system improvable without pretending that every model decision is deterministic.
The system needs a retrieval budget
Budgets should cover model calls, retrieval calls, tokens, wall-clock time, source breadth, and perhaps the number of unresolved conflicts. A budget is not only an infrastructure limit. It is part of the answer’s quality contract.
The system should make degraded outcomes legible. “I found enough evidence” is different from “I reached the time limit,” which is different from “the sources conflict,” which is different from “the request is outside the authorized corpus.”
Failure Modes
Query drift
The loop gradually changes the question while still presenting the result as an answer to the original goal. Preserve the original goal and compare each proposed subquestion against its scope.
First-result anchoring
The first plausible document becomes the working explanation. Require independent evidence, contradiction checks, or alternative queries when the task is consequential.
Retrieval loops
The system keeps searching because every result suggests another search. Enforce step, time, token, and source budgets, and define conditions for escalation or explicit incompleteness.
Chunk context loss
A relevant chunk lacks the document, entity, time period, or section context needed to interpret it. Better chunking, contextualized indexing, hybrid retrieval, reranking, and source fetch tools can help, but they still need evaluation.
Evidence duplication
Several copies of one source are mistaken for independent confirmation. Preserve source identity and relationships so repeated text does not inflate confidence.
Authority collision
A user note, generated summary, current record, and formal policy enter the same context without a visible hierarchy. Label authority and enforce decisions outside the model.
Indirect prompt injection
Retrieved content redirects the model’s next search or action. Treat external content as untrusted data and constrain the capabilities available after retrieval.
Silent truncation
The system retrieves useful evidence but drops it while assembling the next context because of token or response limits. Trace selection and omission, and make the model aware when evidence was truncated.
Citation theater
The final response contains links or source names, but the citations do not support the claims made. Validate claim-to-source relationships and expose uncertainty rather than treating any citation as proof.
Cost spiral
The application adds more retrieval steps to repair weak relevance, then creates unacceptable latency and cost. Improve source selection, query quality, result shape, caching, and evaluation before simply increasing the loop budget.
KNOW / UNDERSTAND / BUILD
KNOW
Know that RAG combines generation with external retrieval, and that retrieval quality includes indexing, chunking, ranking, freshness, access control, and evaluation. Know that agentic RAG is a broad label for systems that make retrieval part of a model-assisted loop.
Know the difference between query rewriting, hybrid retrieval, reranking, multi-step workflows, and genuinely model-directed retrieval. These patterns can be combined, but they are not interchangeable.
UNDERSTAND
Understand retrieval as both an information-retrieval problem and a control-flow problem. Understand how query choice, source selection, evidence state, context assembly, tool contracts, provenance, budgets, and stopping criteria interact.
You should be able to draw the path from an authorized goal to a bounded retrieval action, observed result, evidence update, next query or stop decision, and traceable synthesis. You should also be able to explain why a more agentic loop is not justified when a fixed workflow is clearer and sufficient.
BUILD
Build a read-only retrieval experiment over a small, versioned corpus. Compare:
- one-shot vector retrieval with a fixed top-k result;
- hybrid retrieval with query rewriting or reranking;
- a bounded agentic loop that can choose a source, refine a query, inspect evidence, and stop.
Measure answer quality, claim support, source coverage, conflict detection, retrieval steps, token count, latency, cost, and behavior under stale or injected content. Save the original goal, every query, the selected evidence, omitted results, and the stop reason.
Recommended depth: UNDERSTAND
Build It Once
Start with a read-only evidence ledger before connecting retrieval to external actions. A minimal record for one retrieval step might look like this:
{
  "goal": "identify the checkout latency regression",
  "step": 2,
  "source": "deployments",
  "request": {
    "service": "checkout",
    "environment": "production",
    "observed_after": "2026-09-10T00:00:00Z"
  },
  "result": {
    "status": "complete",
    "identifiers": ["deploy-1842"],
    "returned_items": 1
  },
  "evidence": [
    {
      "claim": "deployment deploy-1842 overlaps the incident window",
      "source_ref": "deployments/deploy-1842",
      "observed_at": "2026-09-12T14:00:00Z",
      "authority": "operational-record"
    }
  ],
  "next": "inspect trace summary for deploy-1842"
}
Then add deterministic controls for authorization, source scope, query syntax, pagination, response size, time, cost, and maximum loop steps. Keep model proposals, retrieved observations, evidence updates, and final claims distinct in the trace.
This small system teaches the important boundary. The model can help decide what to retrieve next. The retrieval service decides what the request is allowed to access. The evidence layer records what was actually found. The application decides whether the result is sufficient for the user or requires review.
Will This Term Survive?
RAG is likely to remain a durable term because it names a lasting architectural pattern: use external memory to supplement model generation. Its implementations will continue to change as context windows, indexes, retrieval methods, and model capabilities evolve.
Agentic RAG is a useful phrase for the current transition, but its boundary is less stable. It may be replaced by terms such as agentic search, retrieval agents, adaptive retrieval, or simply a workflow with retrieval. Some systems described as agentic RAG will turn out to be ordinary query rewriting or multi-stage retrieval.
The durable pattern is iterative evidence gathering under explicit control. A system may use a model to formulate searches, a deterministic workflow to sequence them, or a human to choose the next source. The engineering responsibilities remain: relevance, authority, provenance, freshness, evidence state, budgets, stopping, evaluation, and clear separation between proposal and permission.
The phrase may change. Retrieval as part of the control loop will remain a useful design choice for tasks that cannot be answered by one retrieval pass.
Where It Fits in the Map
RAG to agentic RAG connects the information layer to the control loop of the AI-native application:
- Post 01, Timed Multi-Round Web Lookup: the research loop established that search can be budgeted, iterative, and guided by observations rather than treated as one request.
- Post 02, Agent and Agent Design Patterns: agentic retrieval is one specialized control-loop pattern, and it should not be used where a deterministic workflow is enough.
- Post 03, The Application Boundary Is Weakening: enterprise retrieval crosses application boundaries, so the source owner, authority, scope, and outcome semantics must remain visible.
- Post 04, Tool Calling: retrieval actions are tools with schemas, permissions, budgets, and result contracts. A model-selected search remains a proposal until the runtime validates it.
- Post 05, Model Context Protocol: MCP can expose retrieval resources and tools, while the host still decides which capability and evidence enter the current context.
- Post 06, Context Engineering: retrieval is one way to assemble context. Agentic retrieval adds a lifecycle for discovering, inspecting, carrying, and pruning evidence across model decisions.
- Future memory and evaluation topics: evidence state, durable memory, claim-level evaluation, context caching, and long-running execution extend the same architecture.
The abstraction shift is from treating retrieval as a pre-generation lookup to treating it as a governed information-seeking capability. The model can help navigate the information space. The application must still define where it may look, what it may retain, how much it may spend, and when the evidence is good enough to support a claim.
Sources
- Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks, Lewis et al.: the foundational RAG architecture combining parametric generation with a retriever and non-parametric memory.
- Introducing Contextual Retrieval, Anthropic: chunk context, hybrid retrieval, reranking, retrieval quality, and the trade-off between more evidence and more distraction.
- Building effective agents, Anthropic: the distinction between workflows and agents, and the recommendation to use the simplest sufficient architecture.
- Effective context engineering for AI agents, Anthropic: pre-inference retrieval, just-in-time context, and using lightweight references to load information as needed.
- Writing effective tools for AI agents, Anthropic: narrow tool purposes, meaningful responses, token-efficient retrieval, and evaluation-driven tool design.
- Introducing deep research, OpenAI: a current implementation example of multi-step search, source inspection, pivoting, and synthesis for complex research tasks.
Subscribe
Get new posts by email
Enterprise architecture, AI systems, and platform strategy.